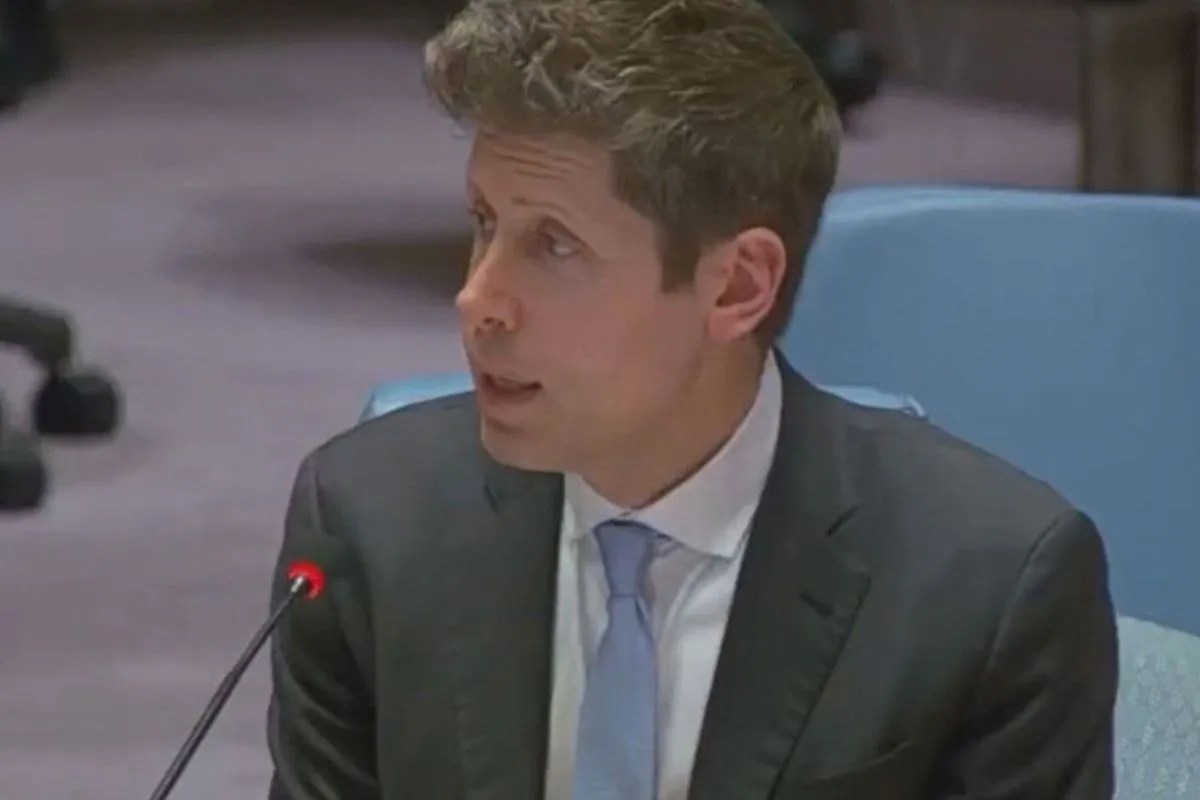
The internet was not built for autonomous visitors. It was engineered for human eyes, human mouse clicks, and human credit cards. When OpenAI chief executive Sam Altman addresses the rising tide of autonomous AI agents scouring web infrastructure, he is not merely discussing traffic logs or API quotas. He is acknowledging a structural crisis at the core of the modern web. Software programs are now moving through digital networks with user-like persistence, scraping data, executing transactions, and interacting with platforms in ways that traditional servers were never programmed to handle.
For months, publishers, e-commerce giants, and cybersecurity professionals have watched automated scripts blur the line between legitimate user behavior and aggressive data extraction. Altman's recent statements regarding transparency and active investigation point to an uncomfortable truth. The companies building foundational models are realizing that their own creations are beginning to stress-test the digital commons. When thousands of autonomous tasks run simultaneously across public databases, corporate firewalls, and login portals, the entire ecosystem begins to strain.
Understanding this friction requires looking past the public relations messaging and examining how web traffic actually moves.
The Architectural Crash Between Humans and Machines
Every major website relies on an implicit social contract. Humans visit pages, view advertisements, occasionally purchase goods, and occasionally contribute content. In return, servers deliver text and images within milliseconds. Autonomous systems break this contract entirely. They do not look at advertisements. They do not browse casually. They execute hyper-efficient loops designed to extract maximum value or training data in minimum time.
When Sam Altman mentions that OpenAI is investigating agent activity with transparency, he is addressing the immediate defensive posture of the web. Media organizations have erected paywalls. Social networks have locked down their APIs. Cloud providers have tightened rate-limiting rules to block unauthorized crawlers. Yet, as models evolve from passive text generators into active agents capable of booking flights, filling out forms, and executing multi-step workflows, simple rate limits are no longer sufficient.
The technical challenge is identification. How does a web server distinguish between a legitimate browser operated by an individual and an autonomous agent acting on behalf of an automated routine? Current security layers rely heavily on heuristics, tracking cookies, and behavioral analysis. But agents can mimic human timing, solve standard verification challenges, and rotate IP addresses across global server networks.
[User Request] ---> [Cloud Firewall] ---> [Application Server] ---> [Database]
                                               |
                                        (Agent Detection)
                                               |
[Autonomous Agent] -> [API Wrapper] -----------+
This structural mismatch creates severe economic pressure. Bandwidth costs rise for platform operators while monetization metrics drop for publishers. If an autonomous program reads an entire news archive in two seconds to summarize it for a user, the publisher gets zero ad impressions, zero subscription conversions, and a higher electricity bill. Altman's acknowledgment of transparency indicates that OpenAI recognizes this asymmetry cannot persist without triggering severe legal and economic blowback.
Economic Incentives And The Scrape Economy
The race for high-quality data has turned the public internet into a battleground. For years, web scraping was viewed as a minor nuisance associated with price aggregators and search engine indexing. Today, it is an industrial-scale operation driven by the massive compute requirements of frontier models.
When autonomous software agents enter the equation, scraping evolves into execution. Instead of just reading pages, these programs interact with dynamic elements. They log into accounts, fill out shipping forms, and navigate user interfaces. This shift terrifies corporate risk officers. An autonomous script making a mistake on a financial portal or an inventory database introduces legal liabilities that static crawlers never faced.
OpenAI finds itself caught between two opposing forces. On one side stands the commercial demand for agents that can perform real-world tasks autonomously. Users want tools that can manage their schedules, shop across multiple retail sites, and resolve customer service disputes. On the other side stands a digital ecosystem aggressively putting up walls to keep automated programs out.
The rhetoric surrounding transparency is an attempt to establish a new operational norm. Traditional web protocols like robots.txt were designed for an era of passive indexing, not active participation. We currently lack a standardized protocol that allows an autonomous agent to announce its identity, respect operational boundaries, negotiate micro-payments for data access, and log its activities transparently for platform operators to audit.
Without such standards, the relationship between AI developers and web publishers will remain adversarial. Every technical adjustment by a platform to block unauthorized interaction is met by a technical workaround from developers trying to keep their systems functional.
The Verification Dilemma And Trust Networks
Fixing this friction requires more than corporate apologies or temporary data-sharing agreements. It requires a fundamental redesign of how digital identity and authorization work on the open web.
If autonomous agents are to become permanent participants in the digital economy, platforms need cryptographic proof of who controls the software and what rules it is programmed to obey. Anonymous or disguised execution works well for malicious hackers, but it is an impossible model for commercial software operating at scale.
Consider a hypothetical marketplace where an automated purchasing assistant must verify its credentials with a merchant server before executing a transaction. If the merchant cannot verify the origin, intent, and operational boundaries of the software agent, the server will drop the connection as a defensive reflex. Trust must be engineered into the protocol layer, moving beyond simple user-agent strings that can be easily spoofed.
This is where Altman's focus on investigation intersects with broader industry standardization efforts. Cryptographic attestation, verified developer signatures, and explicit consent frameworks are slowly moving from academic proposals to urgent commercial necessities. Major technology firms are being forced to build logging and auditing mechanisms that allow third-party platforms to inspect what an agent did, when it did it, and under whose authority it operated.
Yet, technical solutions alone will not resolve the underlying governance questions. Who decides what an agent is allowed to read? How should creators be compensated when their proprietary work trains or informs an autonomous workflow? These questions go far beyond code repositories and server configurations. They touch on property rights, copyright law, and the fundamental economics of digital publishing.
The transition from a human-centric web to a hybrid web populated by billions of autonomous workers will not happen smoothly. The current friction between OpenAI and the broader digital ecosystem is only the opening phase of a much longer realignment. As long as economic value flows through digital networks, the software moving across those networks will continue to test every boundary it encounters, forcing a reluctant industry to rewrite the rules of digital engagement.